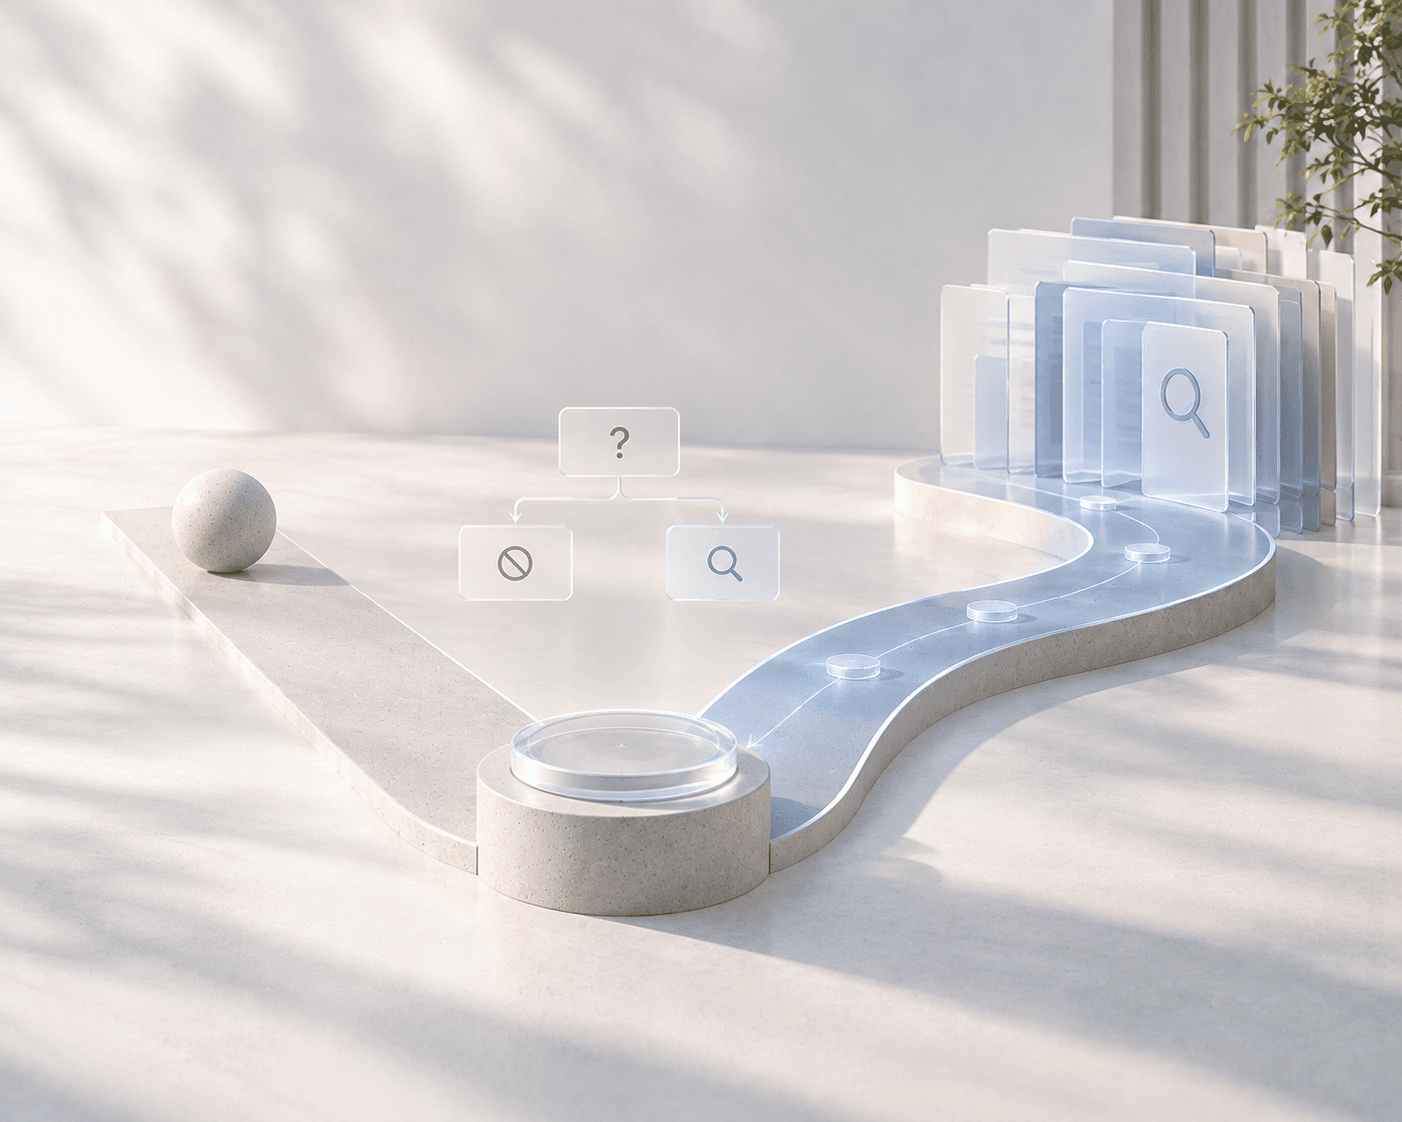
Agentic-RAG vs. naive RAG: why retrieval should be a decision, not a step

Naive RAG retrieves context on every single query, unconditionally; Agentic-RAG treats retrieval as a tool the agent can choose to call, deciding on its own whether a question needs a search at all and, if so, what to search for. That distinction sounds small, but it's the difference between a pipeline that blindly stuffs the top-k chunks into every prompt and an agent that reasons about what it actually needs before it goes looking for it.
Why "retrieve on every query" is the wrong default
A naive RAG pipeline runs the same fixed sequence regardless of the question: embed the query, run a similarity search, take the top-k chunks, and stuff them into the prompt alongside the user's message. This works fine for a narrow class of questions and badly for everything else. Simple factual or conversational queries pay a retrieval tax in latency and token cost for no benefit. Worse, irrelevant retrieved chunks don't just sit there unused — they compete for the model's attention with the actually-relevant context, which measurably hurts answer quality on some queries rather than helping it.
What "agentic" changes
In UnderOcean, retrieval is wired into the agent's reasoning loop as a callable action, not a mandatory pre-processing step. The agent decides, per turn: does answering this require searching the knowledge base at all? If yes, what should the query be — the user's literal question, or a reformulated, more specific one? Is one search enough, or does the first result suggest a follow-up search is needed? None of that is hardcoded; it's part of the same ReAct reasoning loop that decides which other tools to call.
This plays out as a visible reasoning trace, not a black box: you can watch an agent decide not to retrieve for a question it already knows the answer to, and watch it trigger a targeted search — sometimes more than one, refined based on what the first search returned — when a question genuinely depends on your organization's private documents.
What's actually being searched underneath
When an agent (or a flow's dedicated rag_node) does decide to retrieve, both paths call the same
hybrid_search function, which combines two complementary retrieval signals against a knowledge
base's Milvus collection:
- Dense vector search — semantic similarity via embeddings, good at matching meaning even when wording differs.
- BM25 sparse search — lexical/keyword matching via a Milvus
Function-generated sparse vector, good at exact terms, IDs, and phrases that embeddings can blur together.
Combining both catches cases either one misses alone: a semantic match for a vaguely-worded question, and an exact match when the user quotes specific terminology from a document.
For knowledge bases configured in graph_based mode, retrieval can go further with GraphRAG —
Microsoft-style local and global search over an extracted entity graph, with community summaries
generated per Leiden cluster — letting an agent answer questions that span relationships across
many documents, not just similarity within any single chunk. An optional Evidence-Based grounding
mode can also be enabled query-time, without needing to re-ingest anything.
Retrieval as a decision has a cost model, not just a quality one
Treating retrieval as agentic rather than mandatory isn't only about answer quality — it changes the cost and latency profile of a deployment. A support agent fielding a mix of "what are your hours" and "what does section 4.2 of this contract say" questions pays the retrieval cost (an embedding call, a vector search, extra prompt tokens) only on the questions that actually need it, instead of on every single turn regardless of relevance.
FAQ
Does Agentic-RAG mean the agent might never retrieve when it should? The agent's decision is based on its training and the system prompt/guardrails configured for it, same as any other tool-use decision it makes — this is a reasoning choice, not a coin flip, and it shows up transparently in the reasoning trace so you can see (and correct, via prompt or config changes) if it's under- or over-retrieving.
Is Agentic-RAG slower than naive RAG for simple questions? It's typically faster — skipping an unnecessary retrieval call removes latency, it doesn't add any, since the "should I search" decision happens as part of the same reasoning step the agent would take anyway.
Can I force retrieval on every turn if I want naive-RAG behavior for a specific agent?
Yes — a knowledge base's default_trigger_mode can be set to always instead of on_demand,
which reintroduces unconditional retrieval for agents where that's actually the right behavior.
Does this apply to flows, or only standalone agents?
Both. A flow's rag_node performs an explicit, deterministic retrieval step when you want
retrieval to always happen at a specific point in a graph; an agent_node inside the same flow
can still make its own agentic retrieval decisions on top of that.